CairnSecond Brain (RAG over this folder)
What it does for you
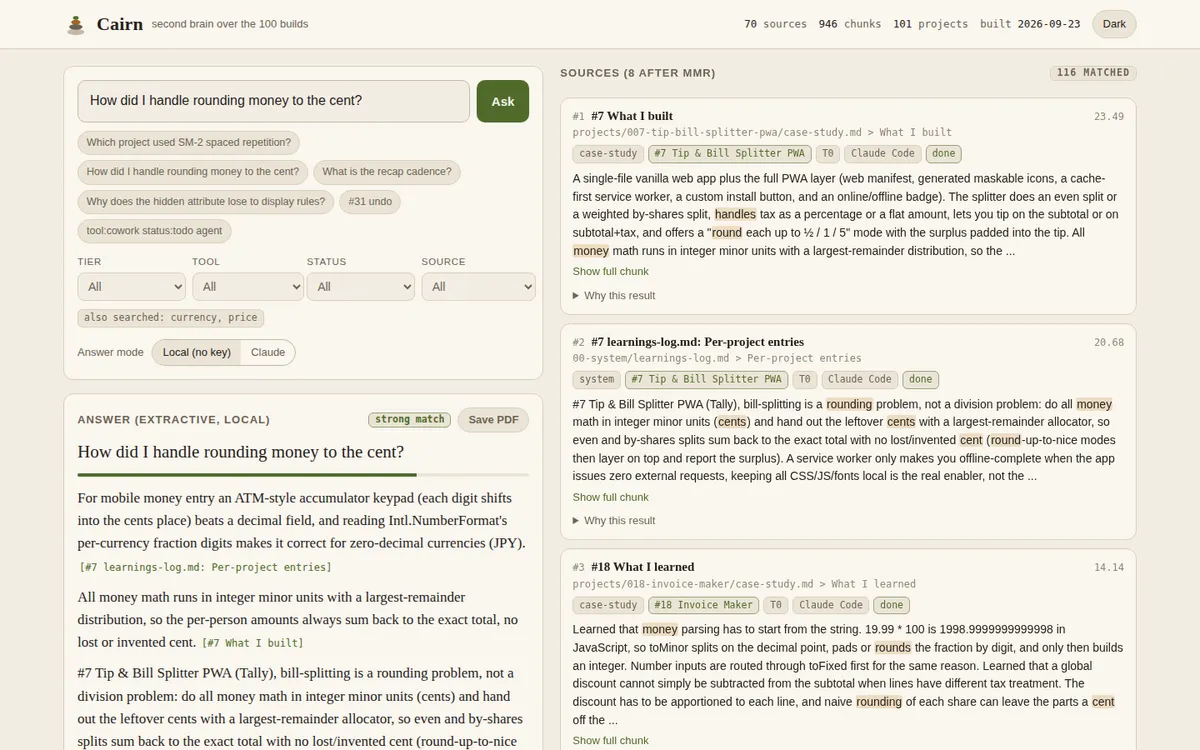
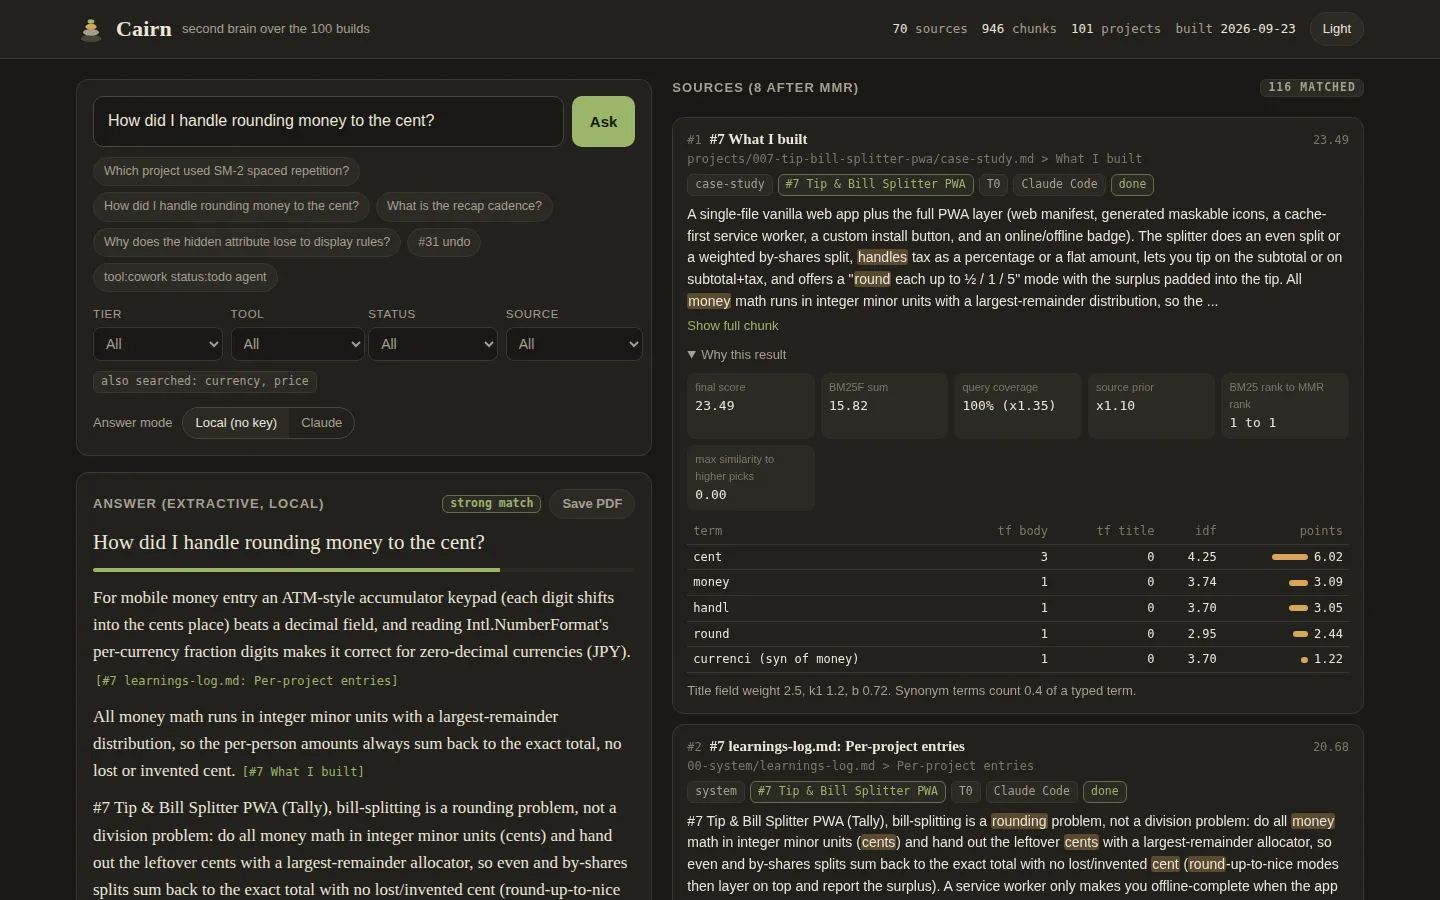
Ask questions across all 100 builds and get answers quoted from the case studies, logs, and tracker, each sentence cited, with BM25F ranking, MMR, filters, and a 25-question eval.
Screenshots
In more detail
Cairn lets me ask plain questions about my own sprint and answers with sentences quoted from my case studies, logs and tracker. Every sentence links to the project and section it came from. Questions like "what does the playbook say about recaps?" used to mean grepping and rereading; now they take a second.
Honest limits
The 25 eval questions came from the same side that wrote the documents, and that flatters any ranker, so those perfect scores need an outside test. The live Claude mode was not called during the build. The demo index is a snapshot, so it has to be rebuilt to see later projects. It runs and passes, but it is a local tool, not a hardened search service.
How I built it
This was one of the Cowork one-shots. I set the spec: ingest the real folder, chunk by heading with metadata, rank with BM25 and field boosts, give cited answers, offer an optional Claude mode with a citation validator, and include a 25-question eval with a pass bar.
Claude Cowork did it in one pass, about 1.2 hours. It read the folder first to learn its shapes, then wrote the core, the indexer, 276 assertions, the eval set, the UI, a small command-line tool and a Cowork skill. It screenshotted the page, read the images back, and fixed what it saw, including one extra parenthesis that stopped the page script.
On the snapshot the index held 946 chunks from 70 sources, and the eval scored hit@1 1.00 and MRR 1.000.
What I learned
- Grounding starts with the data. My folder uses em dashes and the shipped index cannot, so dashes get cleaned at ingest, before chunking. The citation validator checks Claude's quotes against the cleaned text, so cleaning in two places would make a faithful quote fail.
- Scaffolds are the biggest source of noise. 79 unfilled READMEs all said the same "see the row for project N" line. Skipping them, and giving each project-list table row its own chunk, mattered more than any scoring tweak.
- Extractive answers need the heading as context. Asked "what is the definition of done?", the first version picked a status line because it had the word "done". The real answer sat under a "Definition of Done" heading and never repeated the words. Crediting heading terms fixed it, and a floor at 40 percent of the best sentence keeps filler out.
- Name collisions are real in your own data. "Recap cadence" pulls in project 28 because its app is named Cadence. The title boost moved MRR from 0.970 to 1.000, but it also amplifies those collisions, so a "why this result" panel shows the counts.
What carried forward
Cairn only works because every project follows the same template in the same kind of folder, with the tracker as one row per project. I set that structure up for the builders, and it turned out to make the repo searchable too. The quote check here is the same idea as #94's evidence check and #100's fact guard: do not trust the model's claim, check it against the source.
If I took it further
I would add a small embedding reranker over the top 40 BM25 hits for paraphrased questions. I would also add a direct path for number questions, like hours per project, straight from the tracker row.
#098 Built with Claude Cowork September 23, 2026 276 automated checks